


[May-2024] 100% Guarantee Download NS0-593 Exam Dumps PDF Q&A
Kickstart your Career with Real Updated Questions
NEW QUESTION # 20
A customer reports that some of their client computers are unable to access a FlexGroup over CIFS. This problem involves only their older Windows XP clients and some printers and scanners.
In this scenario, which statement Is correct?
- A. These systems use the SMQI protocol which Is an unsupported feature in FlexGroup
- B. FlexGroup requires CIFS shares to be located in qtrees, which these clients do not support.
- C. These systems use Offloaded Data Transfer, which is an unsupported feature in FlexGroup.
- D. FlexGroup requires CIFS shares to use the Continuously Available Feature, which these clients do not support.
Answer: D
Explanation:
FlexGroup requires CIFS shares to use the Continuously Available Feature, which enables transparent failover and recovery of SMB sessions in the event of a node failure or takeover. This feature is only supported by Windows 8 and later clients, and some printers and scanners may not support it either. Therefore, these older Windows XP clients and some printers and scanners are unable to access a FlexGroup over CIFS. Reference = Supported and unsupported configurations for FlexGroup volumes, NetApp ONTAP FlexGroup volumes - Best practices and implementation guide (page 24)
NEW QUESTION # 21
You are attempting to connect a NetApp ONTAP cluster to a very complex network that requires LIFs to fail over across subnets.
How would you accomplish this task?
- A. Configure an equal number of UFs on each subnet.
- B. Configure a I IF failover policy for each subnet inside a single broadcast domain.
- C. Configure VIP LIFs using BGP.
- D. Configure VIP LIFs using OSPF.
Answer: C
Explanation:
A LIF (Logical Interface) is a logical entity that represents a network connection point on a node1.
A VIP LIF (Virtual IP LIF) is a LIF that can fail over across subnets within an IPspace2.
BGP (Border Gateway Protocol) is a routing protocol that enables VIP LIFs to advertise their IP addresses to external routers and to update the routing tables when a failover occurs3.
To connect a NetApp ONTAP cluster to a complex network that requires LIFs to fail over across subnets, you need to configure VIP LIFs using BGP on the cluster and on the external routers3.
This way, you can ensure that the network traffic is routed to the optimal node and port for each VIP LIF, and that the network connectivity is maintained in the event of a node or port failure3. Reference:
1: Logical Interfaces, ONTAP 9 Documentation Center
2: VIP LIFs, ONTAP 9 Documentation Center
3: Configuring BGP on a cluster, ONTAP 9 Documentation Center
NEW QUESTION # 22
You have a 4-node NetApp ONTAP 9.8 cluster with an AFF A400 HA pair and a FAS8300 HA pair with 16 TB NL-SAS drives. You are asked to automatically tier 150 TB of Snapshot copy data from the AFF A400 aggregates to the FAS8300.
In this scenario, which ONTAP license must be added to the cluster to accomplish this task?
- A. S3 license
- B. TPM license
- C. VE license
- D. FabricPool license
Answer: D
NEW QUESTION # 23
You want to assign storage access to an NVMe protocol host.
Which three objects must beconfigured to accomplish this task? (Choose three.)
- A. the NVMe broadcast domain
- B. the NVMe namespace
- C. an NVMe LUN
- D. an NVMe LIF
- E. the NVMe subsystem
Answer: A,D,E
NEW QUESTION # 24
Your customer has mounted an NFS SVM from a Linux client unci performance is very poor. The customer is
certain that they have jumbo frames enabled. They have verified an MTU of 9000 on both the Linux client and
the broadcast domain on the NetApp ONTAP 9.8 cluster.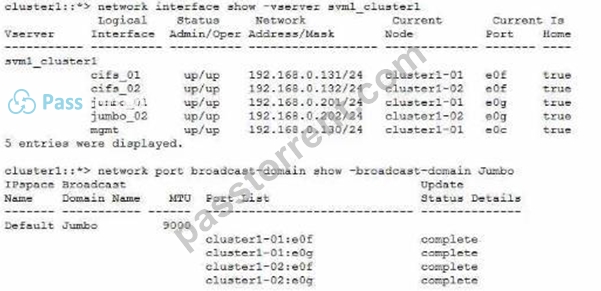
Referring to the exhibit, which ONTAP command will help isolate a possible MTU mismatch?
- A.

- B.
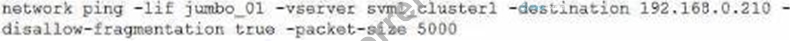
- C.

- D.

Answer: D
NEW QUESTION # 25
Your customer is running a NetApp AFF A800 system with NetAppONTAP 9.8 software and states that their
NS224 shelf is not showing with the correct shelf ID. You analyze the data and the shelf shows an
identification of "1.SHFHUXXXXXXXXXX."
What is the cause of the reported Issue?
- A. The shelf had a disk replaced too quickly.
- B. The shelf has been power cycled.
- C. The shelf was cabled Incorrectly.
- D. A new shelf was added to the controller.
Answer: D
NEW QUESTION # 26
You have a 2-node NetApp FAS2750 switchless cluster with twenty-four 1.8 TB disks that is experiencing
performance issues. Upon investigation, you discover severaltype B consistency points.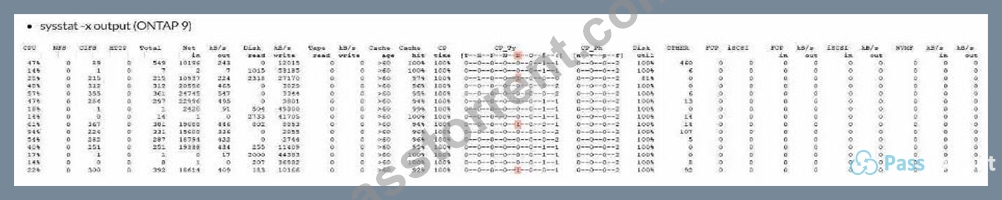
Referring to the exhibit, which corrective action would address these consistency points?
- A. Create additional data LIFs.
- B. Convert the 2-node switchless cluster to a 2-node switched cluster.
- C. Replace the twenty-four 1.8 TB disks with twelve 4 TB disks.
- D. Add an additional shelf oftwenty-four 1.8 TB disks.
Answer: D
NEW QUESTION # 27 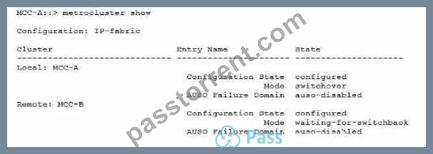
Referring to the exhibit, what do you need to do to return the MetroCluster to a normal state?
- A. Enter the metroclustor switchback command on Site B.
- B. Enter the storage failover giveback command on Site B.
- C. Enter the metrocluster switchback command on Site A.
- D. Enter the storage failover giveback command on Site A.
Answer: C
NEW QUESTION # 28
You have a NetApp ONTAP cluster consisting of four NetApp FAS8200 controllers with two NetApp CN1610 cluster switches running ONIAP 9.8 software. You are receiving several alert messages stating that the cluster network has degraded. After troubleshooting, you determine that the errors are being generated from Node 2, interface e0b.
In this scenario, what should you do first to solve this problem?
- A. Replace the NetApp CN1610 switch that connects to Node 2, interface e0b.
- B. Replace the motherboard on Node 2.
- C. Replace the Twinax cable between Node 2, Interface e0b. and the NetApp CN1610 switch.
- D. Replace both NetApp CN1610 switches.
Answer: C
Explanation:
A Twinax cable is a type of copper cable that is used to connect cluster ports to cluster switches1.
A cluster port is a network port that is configured for cluster communication and data access2.
A cluster switch is a network switch that is used to interconnect the nodes in a cluster and provide redundancy and load balancing3.
A cluster network is a network that enables cluster communication and data access between the nodes in a cluster and external clients4.
A cluster network can be degraded due to various reasons, such as misconfiguration, malfunction, or excessive link errors on the cluster ports or the cluster switches.
Link errors are errors that occur on the physical layer of the network, such as CRC errors, length errors, alignment errors, or dropped packets.
Link errors can indicate a problem with the cable, the switch port, the network interface card (NIC), or the cable connector.
In this scenario, the alert messages state that the cluster network has degraded and the errors are being generated from Node 2, interface e0b.
The first step to solve this problem is to replace the Twinax cable between Node 2, interface e0b and the NetApp CN1610 switch, as this could be the source of the link errors.
Replacing the cable could resolve the issue and restore the cluster network to a healthy state.
If replacing the cable does not solve the problem, then other steps may be required, such as checking the switch port, the NIC, or the cable connector, or replacing the switch or the motherboard. Reference:
1: Cluster network cabling, ONTAP 9 Documentation Center
2: Cluster ports, ONTAP 9 Documentation Center
3: Cluster switches, ONTAP 9 Documentation Center
4: Cluster network, ONTAP 9 Documentation Center
[5]: How to troubleshoot CLUSTER NETWORK DEGRADED error messages, NetApp Knowledge Base
[6]: Cluster network degraded due to high CRC errors on cluster ports, NetApp Knowledge Base
NEW QUESTION # 29
Your customer is running a NetApp AFF A800 system with NetApp ONTAP 9.8 software and states that their NS224 shelf is not showing with the correct shelf ID. You analyze the data and the shelf shows an identification of "1.SHFHUXXXXXXXXXX." What is the cause of the reported Issue?
- A. The shelf had a disk replaced too quickly.
- B. A new shelf was added to the controller.
- C. The shelf was cabled Incorrectly.
- D. The shelf has been power cycled.
Answer: C
Explanation:
According to the NetApp Knowledge Base, adding a second NS224 shelf to an existing stack can cause the first shelf ID to change to the serial number if the cables are not connected properly1. This can also result in a Medium Impact error message: Shelves with both connections via the same SAS path detected2. This situation is not normal for a NetApp AFF A800 system and can affect performance and availability. The cables should be reconnected according to the SAS cabling rules and concepts for shelves with IOM12/IOM12B modules3 and the controller-to-stack cabling worksheet template for quad-pathed connectivity4. Reference = Shelves with both connections via the same SAS path detected, Adding a second NS224 shelf, changes first shelf ID to the serial number, SAS cabling rules and concepts - shelves with IOM12/IOM12B modules, Controller-to-stack cabling worksheet template for quad-pathed connectivity.
NEW QUESTION # 30
You receive the "Unable to connect to the management gateway server"error when trying to connect to a node
management IP.
In this situation, how do you determine whether core dumps are generated for the mgwd user space process?
- A. Log in to the service processor and collect the core dumps from the service processor.
- B. Log in to the clustershell using the node console and collect the core dumps from the clustershell.
- C. Log in to the nodeshell using the node console and collect the core dumps from the nodeshell.
- D. Log in to the systemshell and collect core dumps from thesystemshell.
Answer: A
NEW QUESTION # 31
Your customer installed the shelf firmware for their NS224 shelf over a week ago, and the firmware has not upgraded on shelf 1 module B. The customer wants to know what the next steps would be to get the firmware upgraded after verifying that the shelf firmware is indeed loaded onto the system.
Which step would you perform to complete the firmware upgrade?
- A. Reseat the PSU of the shelf.
- B. Reseat the disk in Bay 0.
- C. Reseat the NSM100 module.
- D. Power cycle the shelf.
Answer: C
Explanation:
The question refers to a scenario where the shelf firmware for an NS224 shelf has not been upgraded on one of the NVMe shelf modules (NSM) after a week of installation.
The NSM is responsible for managing the communication between the drives and the I/O modules (IOM) in the shelf1.
The shelf firmware for the NSM is automatically updated when the NSM is inserted into the shelf or when the system is rebooted2.
If the automatic update does not work, the manual update process involves reseating the NSM, which means removing it from the shelf and inserting it back3.
Reseating the NSM triggers the firmware update and also resets the NSM's state3.
The other options are not correct, because:
B) Reseating the disk in Bay 0 will not affect the NSM firmware update, as the disk is not connected to the NSM1.
C) Power cycling the shelf will disrupt the I/O operations and may cause data loss or corruption4.
D) Reseating the PSU of the shelf will not affect the NSM firmware update, as the PSU is not connected to the NSM1. Reference:
NS224 NVMe drive shelf overview - NetApp
Shelf firmware update process - NetApp
Module firmware upgrade stuck on NS224 shelf - NetApp Knowledge Base
Power cycle a disk shelf - NetApp
NEW QUESTION # 32
You are attempting to connect a NetApp ONTAP cluster to a very complex network that requires LIFs to fail
over across subnets.
How would youaccomplish this task?
- A. Configure an equal number of UFs on each subnet.
- B. Configure a I IF failover policy for each subnet inside a single broadcast domain.
- C. Configure VIP LIFs using BGP.
- D. Configure VIP LIFs using OSPF.
Answer: C
NEW QUESTION # 33
You are trying to deploy a Connector in the AWS cloud from NetApp Cloud Manager. The deployment fails and shows the message 'Insufficient permissions to deploy Cloud Connector". You have verified the AWS access key and the AWS secret key.
In this scenario, what Is the reason that the deployment failed?
- A. No AWS Marketplace subscription is associated with Cloud Manager.
- B. The user lacks the permission to deploy within Cloud Manager.
- C. The Connector can be deployed only in AWS GovCloud (US).
- D. The required Identity and Access Management (IAM) policies were not Installed.
Answer: D
Explanation:
= The Connector is a software component that enables Cloud Manager to manage resources and processes within your AWS environment. To deploy a Connector in AWS, you need to have the correct IAM policies attached to your user account or role. These policies grant the Connector the permissions to perform various actions on your behalf, such as creating and deleting EC2 instances, VPCs, security groups, and so on. If you do not have the required IAM policies, the deployment will fail with the message 'Insufficient permissions to deploy Cloud Connector'. You can find the list of required IAM policies in the Connector deployment policy for AWS. Reference = Creating a Connector in AWS from Cloud Manager, page 3-4.
NEW QUESTION # 34
You Just used the CLI to create a NetApp ONTAP FlexGroup Volume on a NetApp Cloud Volumes ONTAP
instance. After creation, you notice odd behavior in NetApp Cloud Manager.
In this scenario,what Is the reason for this behavior?
- A. The Capacity Management Mode within Cloud Manager should be set to Manual.
- B. Cloud Manager must be used to provision the FlexGroup volume.
- C. The Capacity Management Mode within Cloud Manager should be set to Automatic.
- D. Cloud Volumes ONTAP does not support FlexGroup volumes.
Answer: B
NEW QUESTION # 35
A customer enabled NFSv4.0 on an SVM and changed the client mount from NFSv3 to NFSv4. Afterwards, the customer found that the directory owner was changed from root to nobody.
In this scenario, which statement is true?
- A. The customer did not configure name services on the SVM.
- B. The export policy is not configured properly.
- C. The clients must be restarted to start using NFSv4.
- D. The ID mapping domains do not match between the client and server.
Answer: D
Explanation:
NFSv4 is a network file system protocol that supports security, performance, and scalability features. NFSv4 uses ID mapping to ensure that the permissions of files and directories are consistent across different NFSv4 servers and clients1 ID mapping is the process of translating the user and group identifiers (UIDs and GIDs) of the local system to the user and group names (user@domain and group@domain) of the remote system, and vice versa. ID mapping is done by the idmapd service, which uses the /etc/idmapd.conf file to determine the domain name of the system2 ID mapping requires that the NFSv4 server and client have the same domain name configured in the /etc/idmapd.conf file. If the domain names do not match, the idmapd service cannot map the UIDs and GIDs to the user and group names, and the permissions of the files and directories will be shown as nobody:nobody, which is the default anonymous user3 Therefore, if a customer enabled NFSv4.0 on an SVM and changed the client mount from NFSv3 to NFSv4, and found that the directory owner was changed from root to nobody, the most likely cause is that the ID mapping domains do not match between the client and server. The customer should check and correct the /etc/idmapd.conf file on both systems, and restart the idmapd service and remount the NFSv4 share4 Reference:
1: ONTAP 9 - Network File System (NFS) - The Open Group 2: ONTAP 9 - NFSv4 and NFSv4.1 Enhancements - The Open Group 3: NFSv4 mount incorrectly shows all files with ownership as nobody:nobody - Red Hat Customer Portal 4: NFSv4 mountpoint shows incorrect ownerships as nobody:nobody in CentOS/RHEL - The Geek Diary
NEW QUESTION # 36
Your customer mentions that they have accidentally destroyed both root aggregates in their two-node cluster.
In this scenario, what are two actions that must be performed? (Choose two.)
- A. Install ONTAP from a USB device.
- B. Re-create the cluster from the remote backup.
- C. Re-create the cluster from the local backup.
- D. Rejoin the second node to the re-created cluster.
Answer: A,D
Explanation:
If both root aggregates are destroyed in a two-node cluster, the cluster will be inoperable and the data will be inaccessible. To recover from this situation, you need to perform the following actions:
Install ONTAP from a USB device on one of the nodes. This will create a new root aggregate and a new cluster on that node.
Rejoin the second node to the re-created cluster. This will also create a new root aggregate on the second node and synchronize it with the first node.
Restore the cluster configuration and data from a backup, if available. Reference = ONTAP 9 Documentation Center Storage System Recovery Troubleshooting Recovering from a root aggregate failure
NEW QUESTION # 37
You are optimizing your Cloud Volumes ONTAP. For interoperability and consolidation purposes, you need
to know the storagelimits.
In this scenario, which source should be reviewed?
- A. Hardware Universe
- B. Interoperability Matrix Tool (IMT)
- C. NetApp Cloud Volumes ONTAP Release Notes
- D. Cloud Central
Answer: C
NEW QUESTION # 38
When an administrator tries to create a share for an existing volume named voll, the process fails with an error.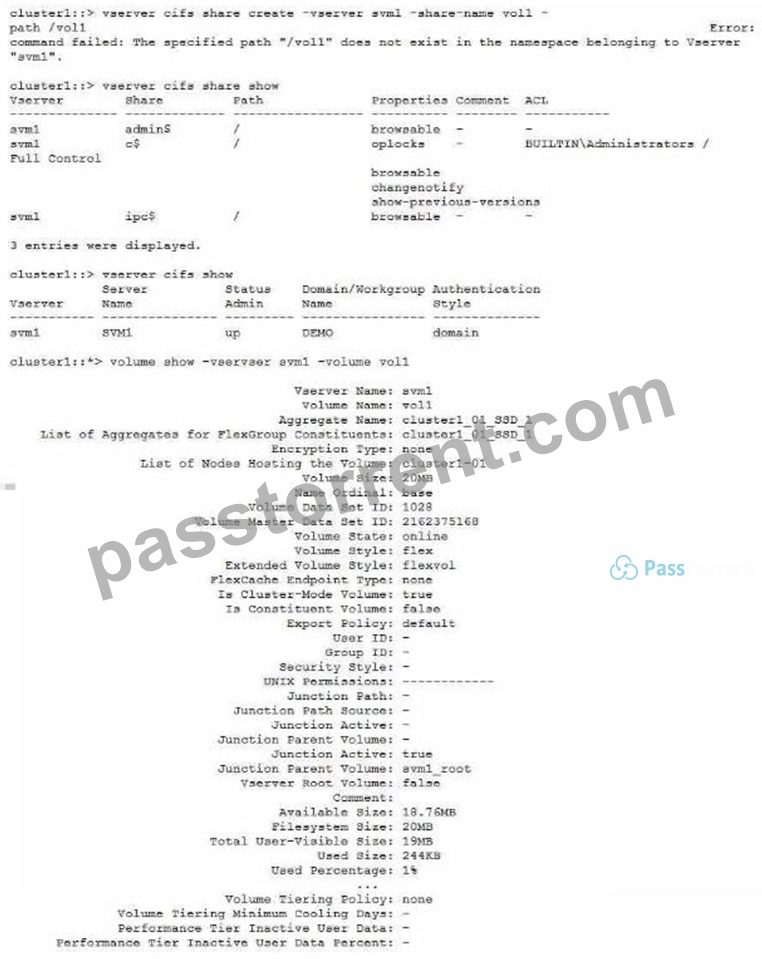
Referring to the exhibit, what Is the reason for the error?
- A. The CIFS service is not in workgroup mode.
- B. The volume has not been mounted.
- C. The CIFS service is not authenticating properly with the domain controller.
- D. The volume must have a type of DP.
Answer: B
Explanation:
The error message indicates that the specified path "/vol1" does not exist in the namespace belonging to Vserver "svm1". This means that the volume "vol1" has not been mounted to the Vserver's namespace, which is required for creating a share. The volume type, the CIFS service status, and the CIFS service mode are not relevant to the error. Reference = https://www.netapp.com/support-and-training/netapp-learning-services/certifications/support-engineer/
https://mysupport.netapp.com/site/docs-and-kb
NEW QUESTION # 39
You have a customer complaining of long build times from their NetApp ONTAP-based datastores. They
provided you packet traces from the controller and client. Analysis of these traces shows an average service
response time of 1 ms. QoS outputconfirms the same. The client traces are reporting an average of 15 ms in
the same time period.
In this situation, what would be your next step?
- A. A sync core should be triggered.
- B. The cluster interconnects should be investigated.
- C. The client that reports high latency should be investigated.
- D. The cluster is responding slowly and requires further investigation using performance archives.
Answer: C
NEW QUESTION # 40
You are trying to deploy a Connector in the AWScloud from NetApp Cloud Manager. The deployment fails
and shows the message 'Insufficient permissions to deploy Cloud Connector". You have verified the AWS
access key and the AWS secret key.
In this scenario, what Is the reason that the deployment failed?
- A. No AWS Marketplace subscription is associated with Cloud Manager.
- B. The required Identity and Access Management (IAM) policies were not Installed.
- C. The user lacks the permission to deploy within Cloud Manager.
- D. The Connector can be deployed only inAWS GovCloud (US).
Answer: C
NEW QUESTION # 41
Which two statements about NetApp Cloud Volumes ONTAP licenses ate true? (Choose two.)
- A. Capacity-based license packages support only single-node configurations.
- B. BYOL licenses are purchased directly from NetApp.
- C. Having an Essentials package enables you to convert to another licensing option.
- D. AWS Marketplace contracts cannot be mixed with BYOL.
Answer: B,C
Explanation:
Having an Essentials package enables you to convert to another licensing option. This is true because the Essentials package is a capacity-based licensing option that allows you to pay for Cloud Volumes ONTAP per TiB of capacity. You can switch to another capacity-based package or to a Keystone Flex Subscription at any time1.
BYOL licenses are purchased directly from NetApp. This is true because BYOL stands for Bring Your Own License, which means you need to obtain a license from NetApp before deploying Cloud Volumes ONTAP systems in any cloud provider2.
Capacity-based license packages support only single-node configurations. This is false because capacity-based license packages support both single-node and HA configurations1.
AWS Marketplace contracts cannot be mixed with BYOL. This is false because you can mix AWS Marketplace contracts with BYOL as long as the license type matches the instance type3. Reference: 1: Cloud Volumes ONTAP licensing | NetApp Documentation 2: Set up licensing for Cloud Volumes ONTAP in Google Cloud - NetApp 3: Set up licensing for Cloud Volumes ONTAP in AWS - NetApp
NEW QUESTION # 42
......
Earn Quick And Easy Success With NS0-593 Dumps: https://www.passtorrent.com/NS0-593-latest-torrent.html
Top-Class NS0-593 Question Answers Study Guide: https://drive.google.com/open?id=1jQ43DLxQfPplAwNQ6m3u1yOrYkpGjnmM