


Latest Verified & Correct Nutanix NCM-MCI Questions & Answers Daily Updated
100% Pass Guaranteed Download Master Level Exam PDF Q&A
What are the steps to follow for the registration of Microsoft Nutanix NCM-MCI Exam
Review the Exam Preparation Guide and Candidate Handbook.
Complete your exam at a mutually agreed upon time/date with your NCX/NPX Program Manager.
Review the Exam Day Checklist.
Email [email protected] to request a unique invitation link to register for your exam.
Benefits Of The Nutanix Certified Expert
NCA is intended for a candidate that has 3 to 6 months' hands-on experience with Nutanix software and is typically a system engineer or similar role.
Nutanix Certified Advanced Professional (NCAP) is an industry-recognized certification that validates a candidate's technical skills with the Nutanix Enterprise Cloud Platform. Achieving NCAP demonstrates proficiency in the design, implementation, operation and troubleshooting.
Nutanix Certified Expert (NCA) is an industry-recognized certification that validates a candidate's technical skills with the Nutanix Enterprise Cloud Platform. Achieving NCA demonstrates proficiency in the design, implementation, operation and troubleshooting of Nutanix Enterprise Cloud solutions.
NEW QUESTION # 10
TASK2
The security team has provided some new security requirements for cluster level security on Cluster 2.
Security requirements:
Update the password for the root user on the Cluster 2 node to match the admin user password.
Note: The 192.168.x.x network is not available. To access a node use the host IP (172.30.0.x) from the CVM.
Output the cluster-wide configuration of the SCMA policy to desktop\output.txt before changes are made.
Enable the Advanced Intrusion Detection Environment (AIDE) to run on a weekly basis for the hypervisor and cvms for Cluster 2.
Enable high-strength password policies for the hypervisor and cluster.
Ensure CVMs require SSH keys for login instead of passwords. (SSH keys are located in the desktop\Files\SSH folder.) Ensure the cluster meets these requirements. Do not reboot any cluster components.
Note: Please ensure you are modifying the correct components.
Answer:
Explanation:
See the Explanation
Explanation:
This task focuses on Security Technical Implementation Guides (STIGs) and general hardening of the Nutanix cluster. Most of these tasks are best performed via the Nutanix Command Line Interface (ncli) on the CVM, though the SSH key requirement is often easier to handle via the Prism GUI.
Here is the step-by-step procedure to complete Task 2.
Prerequisites: Connection
Open PuTTY (or the available terminal) from the provided Windows Desktop.
SSH into the Cluster 2 CVM. (If the Virtual IP is unknown, check Prism Element for the CVM IP).
Log in using the provided credentials (usually nutanix / nutanix/4u or the admin password provided in your instructions).
Step 1: Output SCMA Policy (Do this FIRST)
Requirement: Output the cluster-wide configuration of the SCMA policy to desktop\output.txt before changes are made.
In the SSH session on the CVM, run:
Bash
ncli cluster get-software-config-management-policy
Copy the output from the terminal window.
Open Notepad on the Windows Desktop.
Paste the output.
Save the file as output.txt on the Desktop.
Step 2: Enable AIDE (Weekly)
Requirement: Enable the Advanced Intrusion Detection Environment (AIDE) to run on a weekly basis for the hypervisor and CVMs.
In the same CVM SSH session, run the following command to modify the SCMA policy:
Bash
ncli cluster edit-software-config-management-policy enable-aide=true schedule-interval=WEEKLY (Note: This single command applies the policy to both Hypervisor and CVMs by default in most versions).
Step 3: Enable High-Strength Password Policies
Requirement: Enable high-strength password policies for the hypervisor and cluster.
Run the following command:
Bash
ncli cluster set-high-strength-password-policy enable=true
Step 4: Update Root Password for Cluster Nodes
Requirement: Update the password for the root user on the Cluster 2 node to match the admin user password.
Method A: The Automated Way (Recommended)
Use ncli to set the password for all hypervisor nodes at once without needing to SSH into them individually.
Run:
Bash
ncli cluster set-hypervisor-password
When prompted, enter the current admin password (this becomes the new root password).
Method B: The Manual Way (If NCLI fails or manual access is required)
Note: Use this if the exam specifically wants you to touch the node via the 172.x network.
From the CVM, SSH to the host using the internal IP:
Bash
ssh [email protected] (Replace x with the host ID, e.g., 4 or 5)
Run the password change command:
Bash
passwd
Enter the admin password twice.
Repeat for other nodes in Cluster 2.
Step 5: Cluster Lockdown (SSH Keys)
Requirement: Ensure CVMs require SSH keys for login instead of passwords.
It is safest to do this via the Prism Element GUI to prevent locking yourself out.
Open Prism Element for Cluster 2 in the browser.
Click the Gear Icon (Settings) -> Cluster Lockdown.
Uncheck the box "Enable Remote Login with Password".
Click New Public Key (or Add Key).
Open the folder Desktop\Files\SSH on the Windows desktop.
Open the public key file (usually ends in .pub) in Notepad and copy the contents.
Paste the key into the Prism "Key" box.
Click Save.
Note: Do not reboot the cluster. The SCMA and Password policies take effect immediately without a reboot.
NEW QUESTION # 11
Task 15
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
NEW QUESTION # 12
Task 8
Depending on the order you perform the exam items, the access information and credentials could change. Please refer to the other item performed on Cluster B if you have problems accessing the cluster.
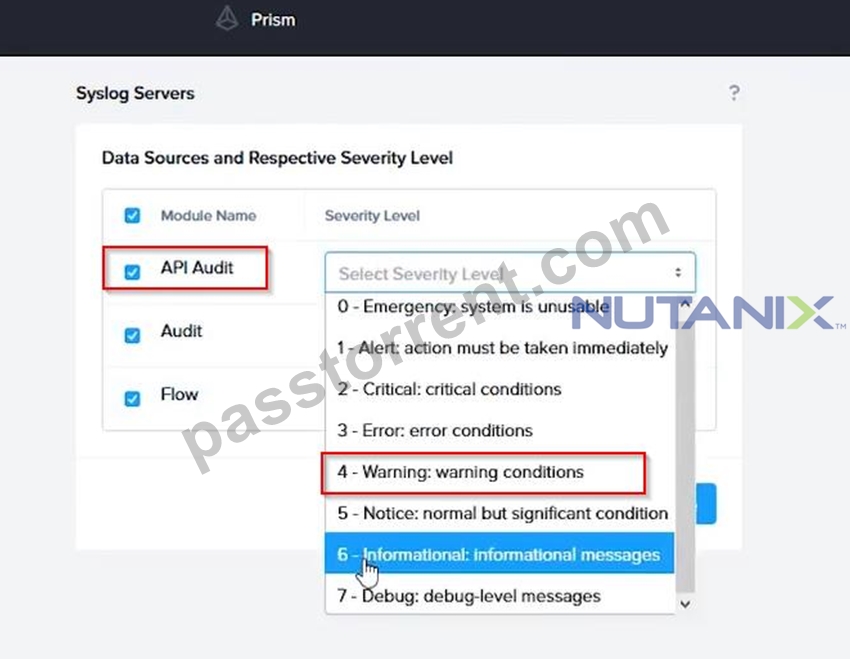
The infosec team has requested that audit logs for API Requests and replication capabilities be enabled for all clusters for the top 4 severity levels and pushed to their syslog system using highest reliability possible. They have requested no other logs to be included.
Syslog configuration:
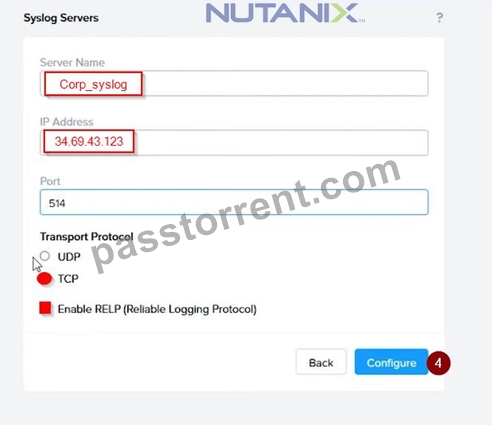
Syslog Name: Corp_syslog
Syslop IP: 34.69.43.123
Port: 514
Ensure the cluster is configured to meet these requirements.
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To configure the cluster to meet the requirements of the infosec team, you need to do the following steps:
Log in to Prism Central and go to Network > Syslog Servers > Configure Syslog Server. Enter Corp_syslog as the Server Name, 34.69.43.123 as the IP Address, and 514 as the Port. Select TCP as the Transport Protocol and enable RELP (Reliable Logging Protocol). This will create a syslog server with the highest reliability possible.
Click Edit against Data Sources and select Cluster B as the cluster. Select API Requests and Replication as the data sources and set the log level to CRITICAL for both of them. This will enable audit logs for API requests and replication capabilities for the top 4 severity levels (EMERGENCY, ALERT, CRITICAL, and ERROR) and push them to the syslog server. Click Save.
Repeat step 2 for any other clusters that you want to configure with the same requirements.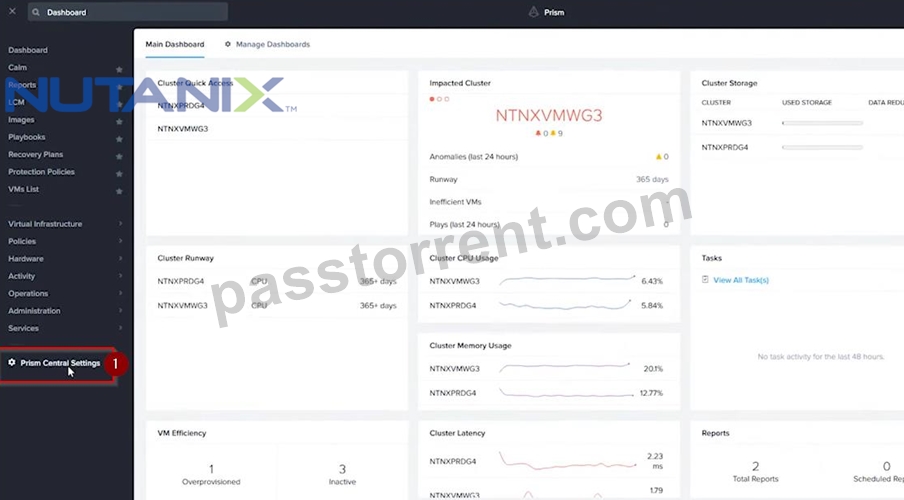
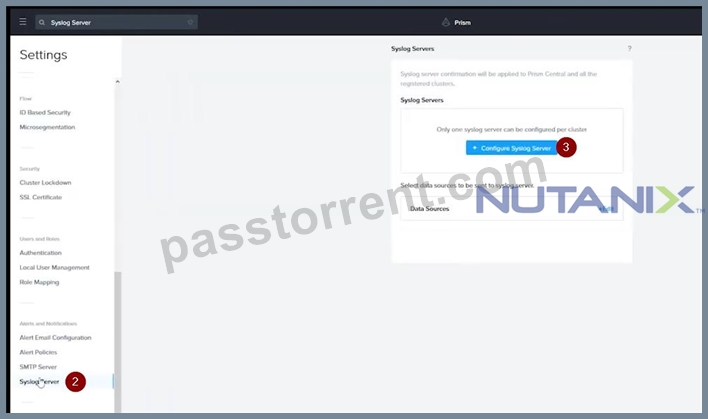
To configure the Nutanix clusters to enable audit logs for API Requests and replication capabilities, and push them to the syslog system with the highest reliability possible, you can follow these steps:
Log in to the Nutanix Prism web console using your administrator credentials.
Navigate to the "Settings" section or the configuration settings interface within Prism.
Locate the "Syslog Configuration" or "Logging" option and click on it.
Configure the syslog settings as follows:
Syslog Name: Enter "Corp_syslog" as the name for the syslog configuration.
Syslog IP: Set the IP address to "34.69.43.123", which is the IP address of the syslog system.
Port: Set the port to "514", which is the default port for syslog.
Enable the option for highest reliability or persistent logging, if available. This ensures that logs are sent reliably and not lost in case of network interruptions.
Save the syslog configuration.
Enable Audit Logs for API Requests:
In the Nutanix Prism web console, navigate to the "Cluster" section or the cluster management interface.
Select the desired cluster where you want to enable audit logs.
Locate the "Audit Configuration" or "Security Configuration" option and click on it.
Look for the settings related to audit logs and API requests. Enable the audit logging feature and select the top 4 severity levels to be logged.
Save the audit configuration.
Enable Audit Logs for Replication Capabilities:
In the Nutanix Prism web console, navigate to the "Cluster" section or the cluster management interface.
Select the desired cluster where you want to enable audit logs.
Locate the "Audit Configuration" or "Security Configuration" option and click on it.
Look for the settings related to audit logs and replication capabilities. Enable the audit logging feature and select the top 4 severity levels to be logged.
Save the audit configuration.
After completing these steps, the Nutanix clusters will be configured to enable audit logs for API Requests and replication capabilities. The logs will be sent to the specified syslog system with the highest reliability possible.
ncli
<ncli> rsyslog-config set-status enable=false
<ncli> rsyslog-config add-server name=Corp_Syslog ip-address=34.69.43.123 port=514 network-protocol=tdp relp-enabled=false
<ncli> rsyslog-config add-module server-name= Corp_Syslog module-name=APLOS level=INFO
<ncli> rsyslog-config add-module server-name= Corp_Syslog module-name=CEREBRO level=INFO
<ncli> rsyslog-config set-status enable=true
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA00e0000009CEECA2
NEW QUESTION # 13
Task4
An administrator will be deploying Flow Networking and needs to validate that the environment, specifically switch vs1, is appropriately configured. Only VPC traffic should be carried by the switch.
Four versions each of two possible commands have been placed in Desktop\Files\Network\flow.txt. Remove the hash mark (#) from the front of correct First command and correct Second command and save the file.
Only one hash mark should be removed from each section. Do not delete or copy lines, do not add additional lines. Any changes other than removing two hash marks (#) will result in no credit.
Also, SSH directly to any AHV node (not a CVM) in the cluster and from the command line display an overview of the Open vSwitch configuration. Copy and paste this to a new text file named Desktop\Files\Network\AHVswitch.txt.
Note: You will not be able to use the 192.168.5.0 network in this environment.
First command
#net.update_vpc_traffic_config virtual_switch=vs0
net.update_vpc_traffic_config virtual_switch=vs1
#net.update_vpc_east_west_traffic_config virtual_switch=vs0
#net.update_vpc_east_west_traffic_config virtual_switch=vs1
Second command
#net.update_vpc_east_west_traffic_config permit_all_traffic=true
net.update_vpc_east_west_traffic_config permit_vpc_traffic=true
#net.update_vpc_east_west_traffic_config permit_all_traffic=false
#net.update_vpc_east_west_traffic_config permit_vpc_traffic=false
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
First, you need to open the Prism Central CLI from the Windows Server 2019 workstation. You can do this by clicking on the Start menu and typing "Prism Central CLI". Then, you need to log in with the credentials provided to you.
Second, you need to run the two commands that I have already given you in Desktop\Files\Network\flow.txt. These commands are:
net.update_vpc_traffic_config virtual_switch=vs1 net.update_vpc_east_west_traffic_config permit_vpc_traffic=true These commands will update the virtual switch that carries the VPC traffic to vs1, and update the VPC east-west traffic configuration to allow only VPC traffic. You can verify that these commands have been executed successfully by running the command:
net.get_vpc_traffic_config
This command will show you the current settings of the virtual switch and the VPC east-west traffic configuration.
Third, you need to SSH directly to any AHV node (not a CVM) in the cluster and run the command:
ovs-vsctl show
This command will display an overview of the Open vSwitch configuration on the AHV node. You can copy and paste the output of this command to a new text file named Desktop\Files\Network\AHVswitch.txt.
You can use any SSH client such as PuTTY or Windows PowerShell to connect to the AHV node. You will need the IP address and the credentials of the AHV node, which you can find in Prism Element or Prism Central.
remove # from greens
On AHV execute:
sudo ovs-vsctl show
CVM access AHV access command
nutanix@NTNX-A-CVM:192.168.10.5:~$ ssh [email protected] "ovs-vsctl show" Open AHVswitch.txt and copy paste output
NEW QUESTION # 14
Task 13
The application team is reporting performance degradation for a business-critical application that runs processes all day on Saturdays.
The team is requesting monitoring or processor, memory and storage utilization for the three VMs that make up the database cluster for the application: ORA01, ORA02 and ORA03.
The report should contain tables for the following:
At the cluster level, only for the current cluster:
The maximum percentage of CPU used
At the VM level, including any future VM with the prefix ORA:
The maximum time taken to process I/O Read requests
The Maximum percentage of time a VM waits to use physical CPU, out of the local CPU time allotted to the VM.
The report should run on Sundays at 12:00 AM for the previous 24 hours. The report should be emailed to [email protected] when competed.
Create a report named Weekends that meets these requirements
Note: You must name the report Weekends to receive any credit. Any other objects needed can be named as you see fit. SMTP is not configured.
A: Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Report Settings option, select Weekly from the Schedule drop-down menu and choose Sunday as the day of week. Enter 12:00 AM as the time of day. Enter [email protected] as the Email Recipient. Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.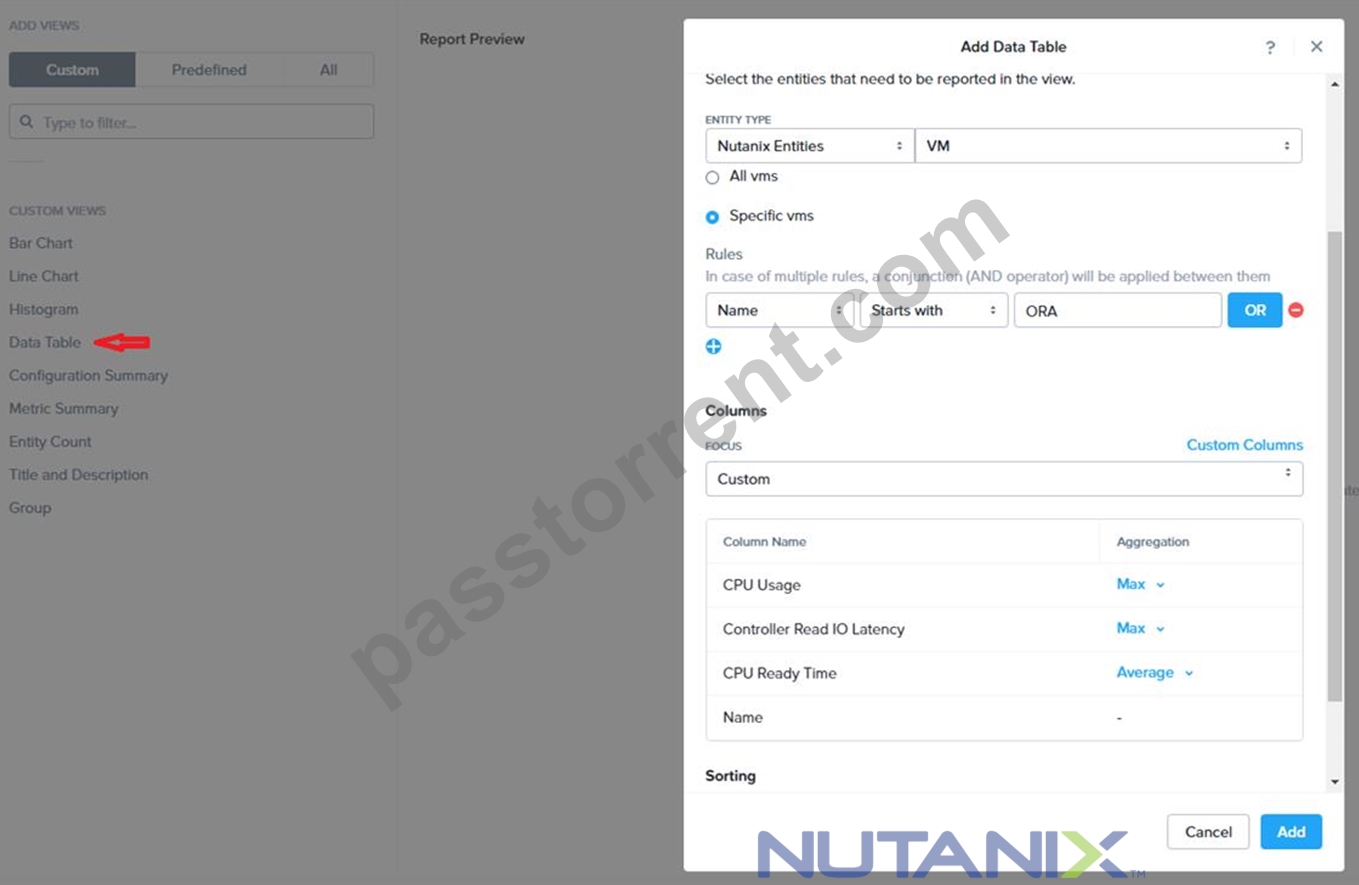
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To create a report named Weekends that meets the requirements, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter Weekends as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select Cluster. Click Next.
Under the Custom Columns option, add the following variable: CPU Usage (%). Click Next.
Under the Aggregation option for CPU Usage (%), select Max. Click Next.
Under the Filter option, select Current Cluster from the drop-down menu. Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Custom Views section, select Data Table again. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, I/O Read Latency (ms), VM Ready Time (%). Click Next.
Under the Aggregation option for I/O Read Latency (ms) and VM Ready Time (%), select Max. Click Next.
Under the Filter option, enter ORA* in the Name field. This will include any future VM with the prefix OR
NEW QUESTION # 15
Task 6
An administrator has requested the commands needed to configure traffic segmentation on an unconfigured node. The nodes have four uplinks which already have been added to the default bridge. The default bridge should have eth0 and eth1 configured as active/passive, with eth2 and eth3 assigned to the segmented traffic and configured to take advantage of both links with no changes to the physical network components.
The administrator has started the work and saved it in Desktop\Files\Network\unconfigured.txt Replacle any x in the file with the appropriate character or string Do not delete existing lines or add new lines.
Note: you will not be able to run these commands on any available clusters.
Unconfigured.txt
manage_ovs --bond_name brX-up --bond_mode xxxxxxxxxxx --interfaces ethX,ethX update_uplinks manage_ovs --bridge_name brX-up --interfaces ethX,ethX --bond_name bond1 --bond_mode xxxxxxxxxxx update_uplinks
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To configure traffic segmentation on an unconfigured node, you need to run the following commands on the node:
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br0-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance-slb update_uplinks These commands will create a bond named br0-up with eth0 and eth1 as active and passive interfaces, and assign it to the default bridge. Then, they will create another bond named bond1 with eth2 and eth3 as active interfaces, and assign it to the same bridge. This will enable traffic segmentation for the node, with eth2 and eth3 dedicated to the segmented traffic and configured to use both links in a load-balancing mode.
I have replaced the x in the file Desktop\Files\Network\unconfigured.txt with the appropriate character or string for you. You can find the updated file in Desktop\Files\Network\configured.txt.
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br1-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance_slb update_uplinks
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2071-AHV-Networking:ovs-command-line-configuration.html
NEW QUESTION # 16
Refer to the exhibit.
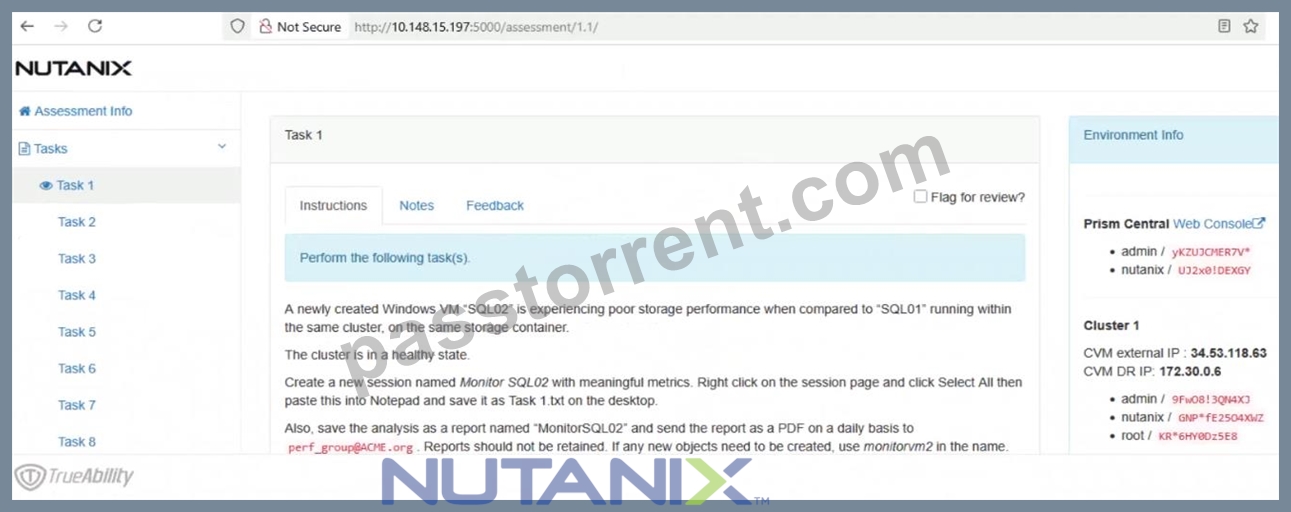
Task1
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to "SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named "MonitorSQL02" and send the report as a PDF on a daily basis to [email protected]. Reports should not be retained. If any new objects need to be created, use monitorvm2 in the name.
Finally, correct the issue within "SQL02"
Notes:
Do not power on the VMs.
While you will be creating a session, you will need to examine the VM configurations to determine the issue.
Do not delete the VM to resolve the issue, any other destructive change is acceptable
Answer:
Explanation:
See the Explanation
Explanation:
This is a classic Nutanix performance troubleshooting scenario. The issue is almost certainly that the VM was created using the wrong Disk Bus Type (IDE or SATA instead of SCSI).
Here is the step-by-step solution to complete Task 1.
Part 1: Analysis and Reporting
Create the Session
Log in to Prism Central (or Prism Element, depending on the exam environment, but Analysis is usually a PC feature).
Navigate to Operations -> Analysis.
Click New Session.
Name: Monitor SQL02
Entity: Search for and select the VM named SQL02.
Metrics: Since the issue is storage performance, search for and add these specific metrics:
Hypervisor IOPS (or Controller IOPS)
Hypervisor IO Latency (or Controller IO Latency)
Hypervisor IO Bandwidth
Click Save.
Save Session Data (Task 1.txt)
Open the "Monitor SQL02" session you just created.
(Per instructions): Right-click anywhere on the chart/data area -> Click Select All.
Copy the selected text (Ctrl+C).
Open Notepad on the provided desktop.
Paste the data.
Save the file as Task 1.txt on the Desktop.
Create and Schedule the Report
While still in the Analysis session, click the Create Report (or "Add to Report") button.
Report Name: MonitorSQL02
Report Settings:
Format: PDF
Frequency: Daily
Email Recipient: [email protected]
Retention: 0 (or "Do not retain", as requested).
Note: If the system forces you to create a new Report object and MonitorSQL02 is rejected, use monitorvm2 as the name per the instructions.
Save/Schedule the report.
Part 2: Diagnose and Fix the Issue
The Issue:
VM SQL02 was likely created with its data disks set to IDE or SATA.
Why this causes poor performance: IDE/SATA are emulated hardware with high CPU overhead and low queue depths (single-threaded).
The Standard: SQL01 (the healthy VM) is using SCSI, which is multithreaded and optimized for virtualization.
The Fix (Steps):
Navigate to the VM list in Prism.
Select SQL02 and click Update (or Edit).
Scroll down to the Disks section.
Identify the data disk(s). You will see the Bus Type listed as IDE or SATA.
Do not delete the VM. instead, perform a disk conversion (destructive change to the disk is allowed, but we want to keep the data).
Method to Convert (Clone to SCSI):
Hover over the IDE/SATA disk to see the path/filename of the vDisk (or write it down).
Click Add New Disk.
Operation: select Clone from ADSF file.
Path: Browse to the storage container and select the file associated with the current IDE disk.
Bus Type: Select SCSI (This is the critical fix).
Index: Ensure it doesn't conflict with existing disks (usually index 1 or higher for data).
Click Add.
Once the new SCSI disk is added, find the original IDE/SATA disk and click the X to remove it.
Click Save.
Note: You do not need to power on the VM to verify. The change from IDE to SCSI allows the VM to use the Nutanix VirtIO drivers for maximum storage performance.
NEW QUESTION # 17
......
NCM-MCI PDF Dumps Are Helpful To produce Your Dreams Correct QA's: https://www.passtorrent.com/NCM-MCI-latest-torrent.html
NCM-MCI Practice Test Dumps with 100% Passing Guarantee: https://drive.google.com/open?id=1cm5eUCRt3ddzjrsTQeVt5kRRQ9B73i67